Category: GEN AI

LLM_log #020: Language Agents — Memory, Reasoning, and Planning

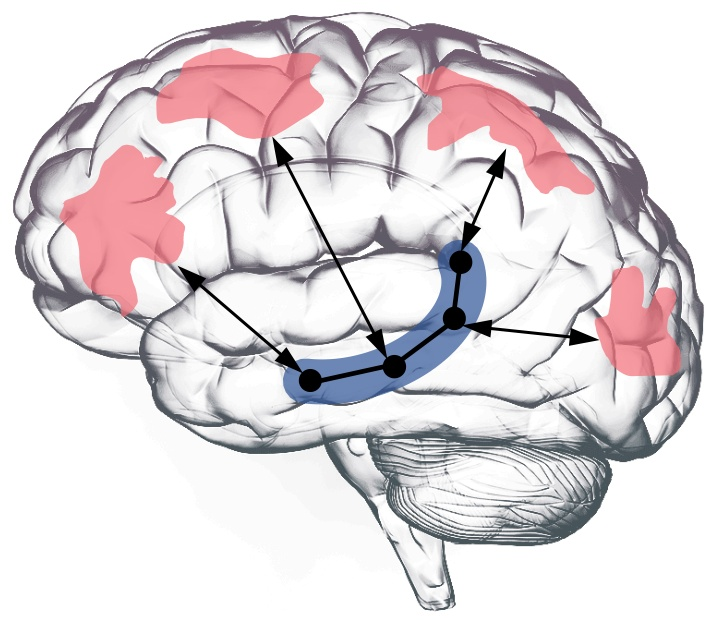
Highlights: Yu Su’s guest lecture in the UC Berkeley CS294-280 course argues language agents are not “LLM + tools” but a new evolutionary stage of machine intelligence. We walk through the agent-first framing and three concrete research pillars — long-term memory (HippoRAG), implicit reasoning (Grokked Transformers), and model-based planning (WebDreamer) — that map directly to classical AI problems re-examined through the lens of LLMs. Agent-first framing: token generation is itself an action; the inner monologue…
Read more

LLM_log #018: Color Harmony Ranking — Three Methods, 500 Living Rooms

Highlights: Can three completely independent methods agree on which living room has the best colors? We rank 500 interior images using Cohen-Or harmonic templates, Hasler-Süsstrunk colorfulness, and CLIP IQA with 44 color-focused prompts — then measure whether they correlate at all. Method 1 — Cohen-Or: K-means palette → saturation-weighted hue histogram → sweep 7 harmonic templates × 36 rotations → H/T/S composite Method 2 — Hasler-Süsstrunk: opponent channels (rg, yb) → colorfulness + 4×4 spatial…
Read more

LLM_log #013: Latent Space — From AutoEncoders to the Engine Inside Stable Diffusion

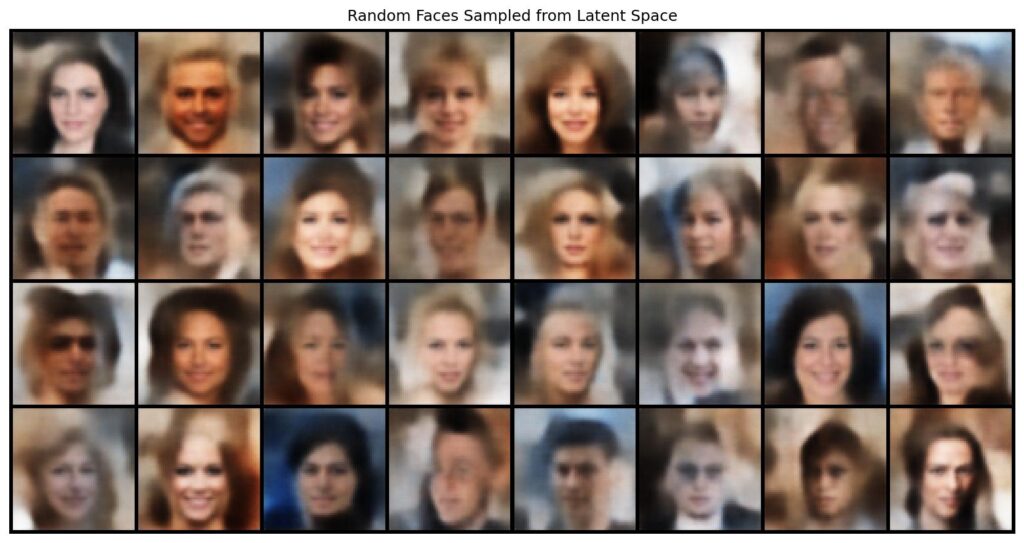
Highlights: Every time you use Stable Diffusion, DALL-E, or Sora, the model never touches a single pixel during its main computation. It works entirely inside a compressed, structured space of floating-point numbers — a latent space learned by a VAE. In this post we build that space from scratch. We start from the simplest possible compression — an AutoEncoder on MNIST digits — understand why it fails at generation, fix it with the VAE’s probabilistic…
Read more

LLM_log #010 Understanding Diffusion Models Through 1D Experiments — From DDPM to Manifold Compactness

Highlights: We implement a complete DDPM from scratch on 1D sine waves — same math as image diffusion, but every intermediate state is plottable. We track 100 parallel trajectories, measure when the model “commits” to a specific sample, then design a controlled experiment that reveals manifold compactness as the key factor determining whether diffusion succeeds or fails. So let’s begin! Tutorial Overview: Why 1D? The Dataset Forward Process Model and Training Generating from Noise What…
Read more

LLM_log #009: An Image is Worth 16×16 Words — From Transformers to Vision Transformers and SWIN

Highlights: In this post, we take a deep dive into the architecture that changed everything — the Transformer — and trace its evolution from NLP into computer vision. We start with the original encoder-decoder model, walk through self-attention and multi-head attention step by step, and then show how Vision Transformers (ViT) apply the exact same mechanism to image patches instead of words. Along the way, we answer the questions that trip everyone up: if we…
Read more