LLM_log #008: CLIP — Understanding Multimodal AI Through Step-by-Step Experiments
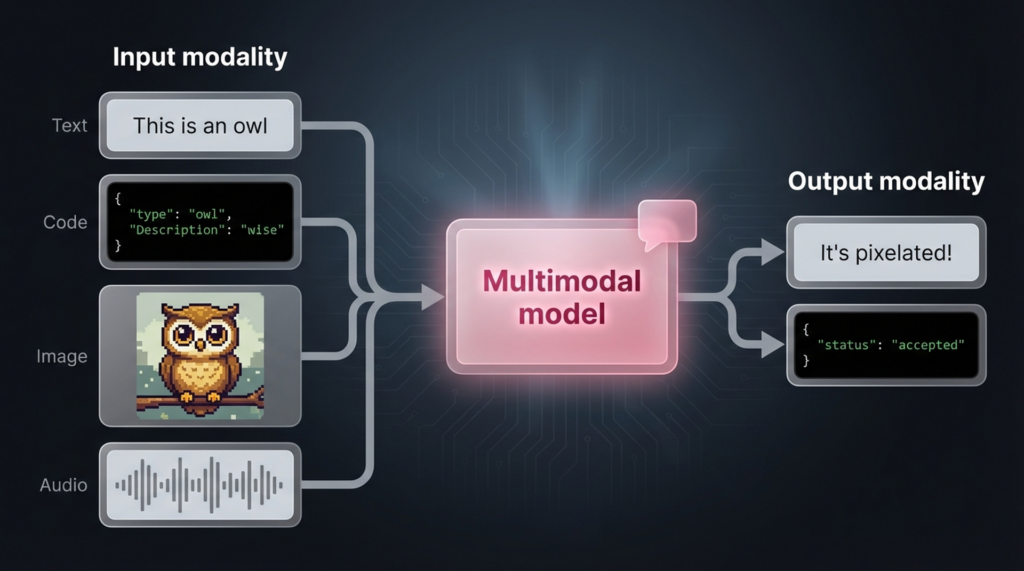
Highlights: In this post, you’ll learn how CLIP connects images and text in a shared embedding space — enabling zero-shot image classification, semantic search, and visual perception scoring without any task-specific training. We start from the ground up with Vision Transformers, walk through CLIP’s contrastive learning architecture, run hands-on embedding experiments, and then push CLIP to its limits with a real-world challenge: can it tell cheap bedrooms from expensive ones using actual house sale…
Read more